


A Reddit citation count records which threads an AI answer put in front of the reader. The question it gets asked is different: whether Reddit shaped what the answer said. This page is for the marketing leader who has to answer that from an AI visibility report, and it shows what each engine’s Reddit number can tell you and where it goes quiet.
Empact Partners is a consultancy that software companies bring inside their marketing teams. Part of what we run there is getting partners discussed where AI engines read before they answer, Reddit threads and list articles included, and measuring which of those places the answers cite. We file it as Generative Engine Optimization, GEO for short.
We measure it on the Empact Panel, our own build, and every number below is that panel run on our own category: 500 buyer questions about hiring help with GEO, content, search and Reddit, put to ChatGPT, Google AI Mode and Claude five times in October 2026. Each engine’s Reddit share there measures a different layer of what that engine did.
A Citation Is What the Answer Showed, and Grounding Is What It Was Built From
When an engine with search answers a question, a report tends to fold several events into one. The engine’s searches fetch pages. The answer draws on some of what came back. It shows a few of those pages as links. A citation count measures only the last of those, and the question people ask of it lives in the middle.
| Layer | What it is | What can see it | What it proves |
|---|---|---|---|
| Retrieval | The pages the engine’s searches returned while it answered | The engine; some collection routes keep a list or a count | The engine had the page in front of it |
| Grounding | The part of what came back that the answer drew on | Only the engine | Nothing outside the engine can show it |
| Citation | The links the answer displays | Any tracker that stores the source list | The answer chose to show that page |
| Influence | How much one page changed what the answer said | Nothing a tracker holds | Unknown |
| Training | What the model learned before anyone asked | Nothing a tracker holds | Unknown |
A tracker that stores only the source list fills the citation row and nothing else. The rows that answer the question people bring to a Reddit number, grounding and influence, are blank for everybody, us included. A fetched page proves access and a shown page proves selection, and neither one proves weight.
So before you read any Reddit share, find out which of those rows your tracker fills for each engine. Ours fills a different one for each of the three.
Our Panel Records a Different Layer on Each Engine
The column in our panel is called citations for all three engines. What sits in it depends on what each collection route hands over, and the routes hand over different things. For Google AI Mode we keep the answer and the sources it shows, 3.4 per answer on average, and nothing about what it fetched.
For ChatGPT we keep the sources the answer cites, 9.2 per answer, and a count of the pages its searches returned, 18.6 per answer, without the list of which pages they were. We ask Claude through its API with web search on, and for Claude we keep the pages its search returned, about nine per answer, and none of the citation marks in its answer.
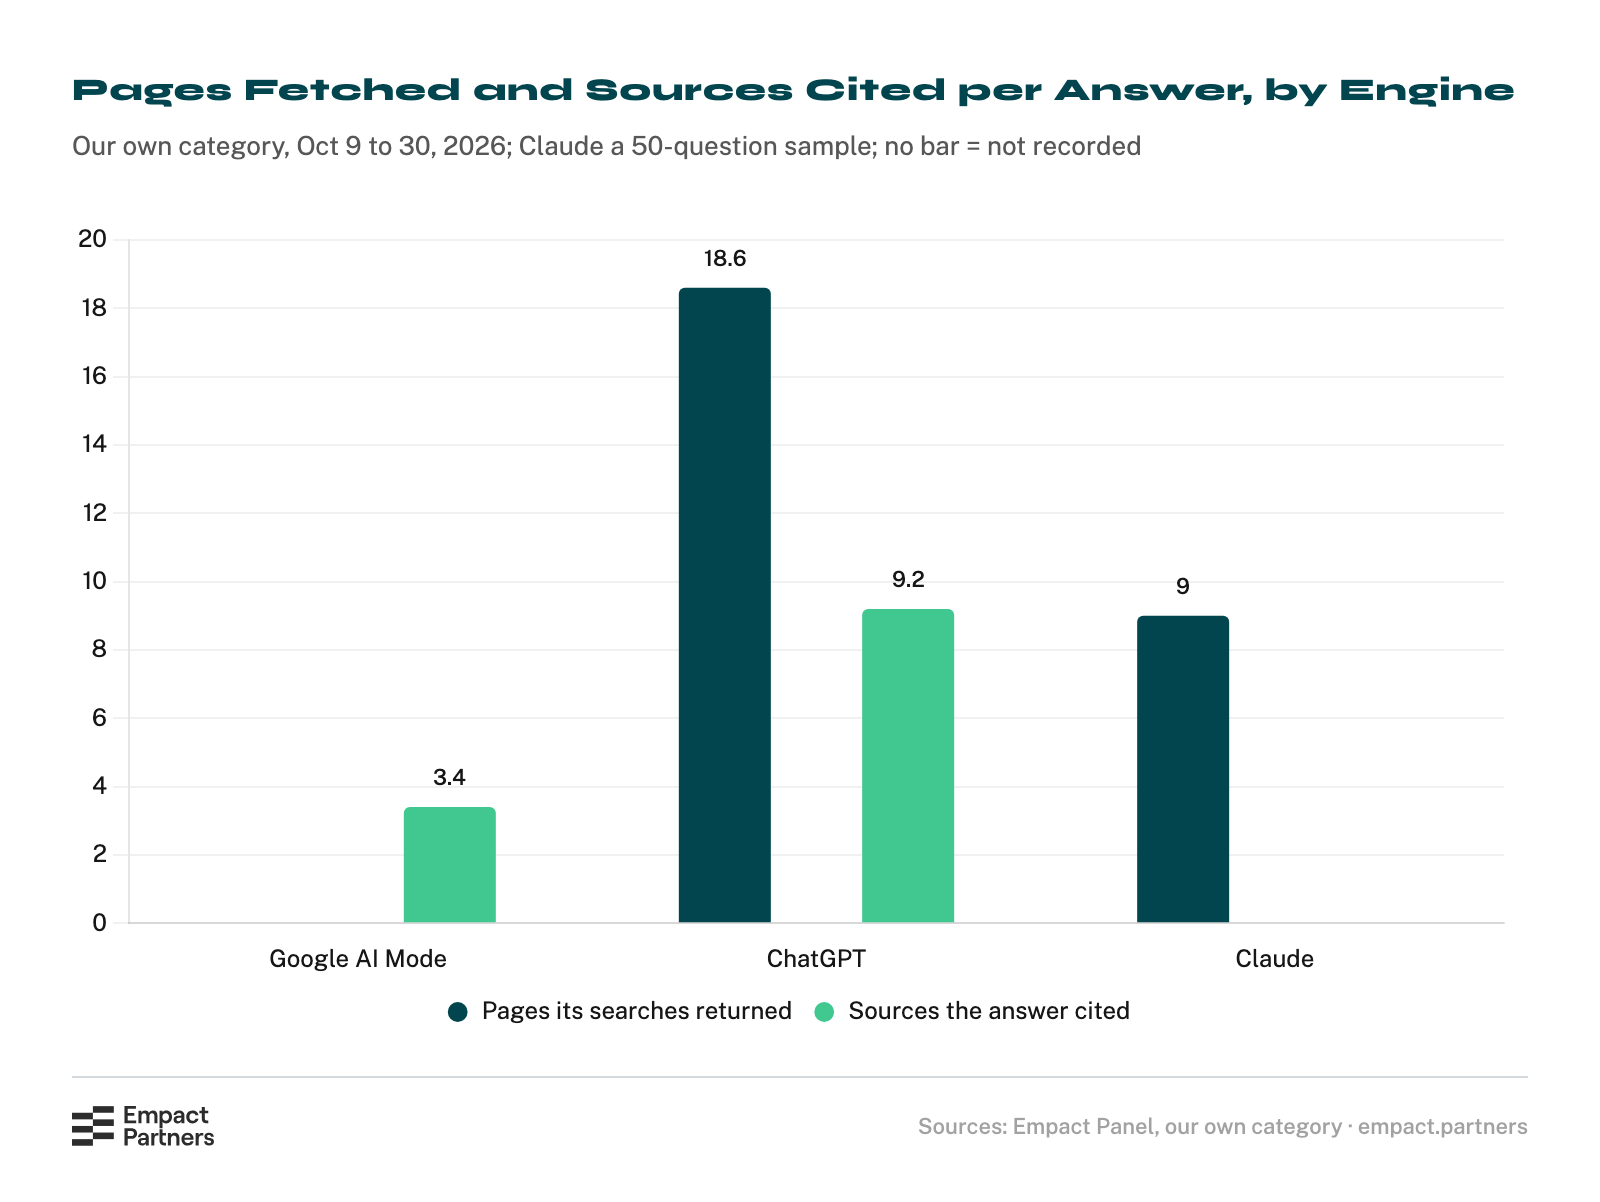
So one word means three things. On AI Mode it is what the answer showed. On Claude it is what the search fetched. On ChatGPT it is what the answer showed, with a number beside it for what was fetched. Nobody chose that split. It is what each route returns, and any tracker reading these engines through the same kind of route inherits it.
Ask yours which layer each engine’s column holds before you compare two engines on it. Two columns holding different layers will disagree even when the engines behave the same.
On Our Questions, Claude Never Fetched Reddit and ChatGPT Rarely Showed It
Read the Reddit shares by layer and the three engines stop being three readings of one thing. The last column leaves out our 75 questions about Reddit marketing, because an answer about Reddit marketing cites Reddit by subject.
| Engine | What the panel holds | Reddit in cited answers | Without the Reddit questions |
|---|---|---|---|
| Google AI Mode | Sources shown | 34.8% (859 of 2,467) | 29.7% (622 of 2,094) |
| ChatGPT | Sources shown, and a count of pages fetched | 11.4% (270 of 2,370) | 0.8% (16 of 2,020) |
| Claude | Pages fetched | 0 of 245 | 0 of 205 |
Claude’s zero is the strongest negative we hold, and narrower than it looks. Its searches returned 2,251 pages and none was on reddit.com, but that is one 50-question sample asked five times through the API, not the Claude app. On those fifty questions no Reddit page reached Claude while it answered. What it learned in training is outside our record.
ChatGPT’s zero is a different zero. Leave out the Reddit questions and it showed a Reddit thread in 16 of 2,020 cited answers, never above 1.2% in any run. Its searches returned about twice as many pages as its answers cited, and the record keeps only how many. Whether Reddit was among them is a question the count cannot answer.
Google AI Mode is the engine that shows Reddit often: in about three of every ten cited answers even with the Reddit questions out, between 25.3% and 32.6% in each run. It is also the engine whose fetching we see nothing of, so how much Reddit it read and then dropped is unknown.

A Fetched Page Is Evidence of Access, Not of Use
The practitioner line on ChatGPT is that it fetches Reddit threads and declines to cite them. On our record that describes the engine, not Reddit. In each of four runs its searches returned between 17.7 and 19.6 pages per answer while the answers cited between 7.8 and 10.5, so a fetched page that never got cited is the ordinary case on that engine.
The returned list is not the whole picture either. Our collection keeps one ChatGPT answer a run whole, and in two of those four answers the engine cited pages that were not in the list its searches returned. Either it drew on pages it already held or the list we receive is incomplete, and both readings make the retrieval layer partial.
Both counts leave influence where it started, unknown from the report. A tracker that says Reddit works invisibly in ChatGPT is reading a count it has no page names for. A tracker that says Reddit does nothing there is reading a column that cannot see training. We say neither.
What can bear on influence, and how much each one shows
Four tests get closer than a citation count, and each shows something narrower than influence:
Write the Reddit Line With Its Layer and Its Denominator
None of that needs a new tool. It needs five checks on the report you already have, in this order:
- Name the layer per engine. Ask your tracker, or read its documentation, for what each engine’s column holds: shown, fetched, or both. A column that holds different layers on different engines cannot rank them.
- Take the Reddit questions out. With our 75 questions about Reddit marketing in, ChatGPT shows Reddit in 11.4% of cited answers. Without them it is 0.8%, and the larger number was mostly the subject talking.
- Write the denominator into the sentence. Reddit in 34.8% of AI Mode’s cited answers and Reddit as 13.6% of its citations are both true. One counts answers, the other links, and AI Mode shows few links per answer, so its answer share runs high. Semrush’s study of 248,000 Reddit posts cited in AI answers, last refreshed in October 2025, finds the split running the other way on Perplexity: Reddit in 3.5% of answers and 4% of citations. Never subtract one from the other.
- Read each zero by its layer. A zero in a fetched column means the page never arrived. A zero in a shown column means it never appeared. A zero on an engine whose fetching you cannot see says nothing about fetching at all.
- Write only what the line allows. “Reddit was shown in about three in ten of Google AI Mode’s answers to our buyer questions this month” tells you which threads to read and which engine to watch. It does not say Reddit drove those answers, and it does not size a budget.
The five checks transfer to your category because the layers belong to the engines and the routes. Our shares do not transfer. In our category Reddit is also a service that companies sell, so it turns up in answers as a subject as well as a source, and a category where nobody sells Reddit work will read differently.


Weigh that knowing we sell Reddit work. A count that cannot justify cutting a Reddit program cannot justify growing one either, and growing one is what would pay us.
All five checks fit in an afternoon. The series behind them does not: the same questions asked every week on each engine, the fetched layer kept wherever an engine hands it over, and somebody who reads the shown threads and knows which hold buyers. That takes a quarter and an owner, and it is the part we run for more than a dozen partners every week.
Citations Tell You Where to Look, and Buyers Tell You Whether It Worked
In our GEO work the panel is the map. Each week it shows which Reddit threads the engines put in front of a partner’s buyers, and the senior consultant who owns the partnership reads them. A thread that keeps being shown without the partner in it is the next piece of work.
That work shares a roadmap with the list articles the same engines cite, under Search Everywhere Optimization, our search work across every surface buyers ask on. Whether any of it pays is read in the threads: who is asking, who is buying, and what the signup question says. That is why we steer partners’ Reddit work by its buyers.
If your report carries a Reddit number and nobody in the room can say what it means, book a call with me, and let’s see whether this is work we could do together.


