You pasted the brand brief into a fresh Claude session this morning, the page and a half in Notion called Brand Voice v4 (USE THIS ONE) that has said no em dashes, in bold, since February. The draft came back with three em dashes, an exclamation mark in the second line, and your customers described as users.
You fixed all three, the same three as last week, and a colleague fixed them in their own session an hour ago without either of you knowing. The brief was there the whole time. What failed is that yesterday’s fix had nowhere to live, so the model starts every morning from the same page and makes the same three mistakes.
Empact Partners runs Content Marketing for software companies, AI-native: Claude drafts, and the consultant who owns each partnership decides the angle and when a piece is ready. We are a go-to-market consultancy, and skills are how that consultant’s standard reaches every draft. Running them taught us which corrections belong in one.
The Minutes Get Counted, and the Corrections Compound
The minutes are real, and they are what everyone counts. Before I built my first skills, I spent about the first fifteen minutes of a Claude session setting context: the voice, the formatting rules, which partner results I could cite, and which words to avoid.
Claude Code logged 261 sessions that I started by hand in the last thirty days. At fifteen minutes each, that is about 65 hours a month of briefing, which is the multiplication every vendor selling skills will happily do for you.
Practitioners have learned to discount it. When a post in r/DigitalMarketing claimed five Claude skills had cut 23 hours a week of marketing work, the two top replies were these.
“this is a terrible marketing post.” — u/StxtoAustin, r/DigitalMarketing, Apr 2026
“I was going for reddit but i think i opened Linkedin by mistake” — u/searchpriest, r/DigitalMarketing, Apr 2026
Both replies have a point beyond the tone. The minutes are the cost you can see, so they get counted. The cost nobody counts is the correction: it has to be made again in every session, by everyone, and when somebody forgets, it ships.
We have the receipt from our own site. When we counted in September, our 44 live articles carried 396 em dashes across 23 of the pages, while three of our own house documents set a limit on them and each set a different one. The rule lived in documents no session opened while it wrote.
Nine of my pages on that list were written in March from briefs that banned the dash outright, and none of the nine carries one. A page I published nine days before them carries 31. The difference I can point to is where the rule lived: in front of the model while it wrote, or in a document it never opened.

The obvious answer is that Claude remembers things now. It does, so I checked what mine remembers. My Claude Code memory holds 426 notes, and 110 of them are corrections and preferences I have given it.
The rule against em dashes is in there seven separate times, written in different weeks for different partners and publications, and an eighth note says the ban does not apply to one of them. That is memory doing its job: it keeps what each conversation decided to keep, and nobody reads all 426 to make them agree.

A Skill Is a Folder Claude Opens When the Task Arrives
So the correction needs a home that every session reads and somebody owns. That is what a skill is: a folder with one instruction file in it, and at the top of that file a name and a short description that Claude matches each request against.
By Anthropic’s own documentation, Claude keeps only those two lines in view for each skill until a request matches, which is why a team can install dozens. Then it reads that skill’s instructions, and opens anything else in the folder, a reference file or a script, only when the task needs it.
That changes what a brief can be. The median skill on my laptop runs to 768 words, more than anyone retypes. The standard behind one of our educational articles loads about 40,000 words across twelve files, a brief nobody would write by hand, read every time its task comes up. It changes what happens to yesterday’s fix, too:
| When Claude reads it | What happens to yesterday’s fix | Who can change it | |
|---|---|---|---|
| A saved prompt | When you paste it | Lost, unless someone goes back and edits the prompt | Whoever has the doc open |
| A Claude Project | In every chat inside that one project | Kept if someone writes it into the instructions; other projects never see it | Anyone who can edit the project |
| Memory | When the model judges a note relevant | Kept as one more note, beside any it contradicts | Mostly the model, and you, a note at a time |
| A custom GPT | Only inside that GPT | Kept only if its builder reopens the instructions, until the GPT retires | Its builder |
| A skill | In any chat where a request matches its description | Written into the file as a rule, a fact, or a check, with its reason | Its owner, with a history of every change |
A Project is the honest rival, because its instructions are always on inside it. They are also read in full in every chat, so they stay short. A skill is read only when its task arrives, so it can carry the whole standard, follow the task into any chat, and bring a check that does not depend on the model remembering anything.
The Custom GPT Was the Equalizer, and OpenAI Is Retiring It
For a content team, the real rival to a skill was the brand-voice GPT, which anyone could build in ten minutes and share with a link. It leveled the field, because every team could have one. OpenAI’s own help center now says custom GPTs are scheduled to retire on December 11, 2026.
The migration turns each GPT’s instructions into a skill inside a plugin and its knowledge files into reference files, so ChatGPT teams get skills without switching anything. What it cannot move is the corrections. Those lived in the chats, where somebody fixed the same paragraph every week, and chats are not part of the migration.
The converted file has a second surprise in it. A GPT’s instructions were always on: open the GPT and they applied. A skill loads only when the request matches its description, and nobody wrote a GPT’s instructions with a description in mind. One heavy user who migrated theirs described the result:
“It kept turning itself off because it has its own discretion whether it thinks that plugin/skill is needed or not.” — u/616ThatGuy, r/ChatGPT, Sep 2026
A skill that switches itself off has a description that says what it is and never when it is needed. Ours list the phrases people type when they want the work done: write an Empact Zone article, resume this draft, let the team know. A skill triggered by the words people use is a skill that gets used.
With the format converging, the decision left is where the skill runs. We run ours in Claude Code, where a skill is a folder on your own machine with the same access as any other program, so ours do the work as well as the briefing: the checks run on the draft, the publish goes to the CMS, and the record lands in git.
The em-dash rule from September is one of those checks now, a script that refuses any draft over budget. Nobody has to remember it, and no house document gets to disagree with it.
Your First Skill Is the Fix You Have Made Twice
The usual advice is to build a skill for the task you do most often. Start somewhere more specific: the correction you have made twice. A second correction means the first one taught nobody anything, and it is the clearest signal there is that a rule is missing.
Three signs you have found one:
Rank what you find by what the mistake costs when it ships, not by how often you see it. A stray em dash costs a raised eyebrow. A claim about your product that legal never approved costs a conversation you do not want to have, and it belongs in a skill before anything else.
The skills nobody thinks to build
Every list of Claude skills for marketers names the same jobs: keyword research, briefs, copy, ads, reports. Ours include those, and they are not the ones that changed how we work.
Then there are the less glamorous ones, which file expense claims and book leave on the team calendar. Most of what a standard protects happens around the copy, not inside it.
What Goes in the File Decides Whether It Keeps Working
Building the skill starts with the brief you already paste. Put it in the folder and sort every line by kind, because each kind belongs somewhere different. Anthropic’s documentation divides a skill the same way: instructions for judgment, code for whatever has to be reliable, and reference files for facts.
The sort we use puts a line from a typical brand brief in each row:
| A line from the brief | Where it goes | Why |
|---|---|---|
| “Write like a senior practitioner talking to a peer, never down to them.” | The instruction file, as a principle with its reason beside it | A rule with no reason gets applied too literally, or quietly dropped |
| “The Growth plan includes SSO. Starter does not.” | A reference file the skill reads when a draft mentions plans, dated | A stale fact in the instructions gets believed every single time |
| “Never name a customer who has not signed a release.” | A script that checks the draft against the list of approved names | The model follows a sentence most of the time, and a script every time |
| “Here is a paragraph we love.” | The instruction file, rewritten into a different industry from yours | The model copies examples word for word |
| “Aim for one joke every 300 words.” | Nowhere | The model treats it as a quota |
The last two rows are the ones the guides leave out, and both come from our own standard. When four of our articles were rejected in September, every one of them had carried the standard’s own example sentences onto the live page, the worst of them in thirty-nine places.
The examples now come from other trades, land surveyors and dental practices mostly, and a check refuses any draft that shares a seven-word run with one. Counts went the same way. The content doctrine we inherited was roughly sixty percent quotas, a schedule for jokes among them, and it produced exactly the jokes a schedule produces.
You can write down the register you want: dry, plain, and aimed at the practice, never the person. Write down how often, and you get a joke every few paragraphs whether the paragraph wanted one or not.
Write the description last, and hardest
The description is the only part of a skill Claude reads before deciding whether to use it, so it has to say what the skill does and when, in the words your team uses when it asks.
“Brand voice guidelines” describes a document, and almost nothing a person types will match it. “Use when drafting anything a customer will read: blog posts, emails, landing pages” describes a moment, which is what a request gets matched against.
The description is also the fix for the GPT that switched itself off. A migrated instruction box describes what the assistant is, because a GPT never had to say when it was needed. Write the when into the description, and the skill has something to match.
Every Fix Goes Back Into the File, or the Skill Stops Being Right
A skill is right on the day you write it and drifts from there, because your standard moves and the file does not. The ones that hold up get edited on the day a draft comes back wrong. The loop we run is small enough for a team of one:
- Log every fix first. The moment you make it, write one line: what was wrong, what you changed, and why. It is a note, not a rule yet.
- Promote it the second time. When the same fix turns up again, make it a rule in the skill, with the reason written beside it.
- Then make the always-wrong a check. If the rule is broken the same way every time, turn it into a check the draft has to pass before anyone reads it.
- Strike retired rules, never delete them. When a rule stops being true, strike it through with the date and the reason, so the next person with the same idea finds out it was tried.
- Last, rerun recent drafts. After any change, rerun the last few drafts the skill produced and read them against the new version.
OpenAI’s migration notes ask the owners of converted GPTs for the same final test: a few familiar prompts and at least one harder case.
Waiting for the second time stops a skill swallowing every opinion anyone ever had. In its first week, as the founder ruled on its first articles and rejected four, our standard went from 204 written rules to 243 and from 31 checks to 66. In the four weeks that followed, 63 notes came in, and the standard gained six written rules and three checks.
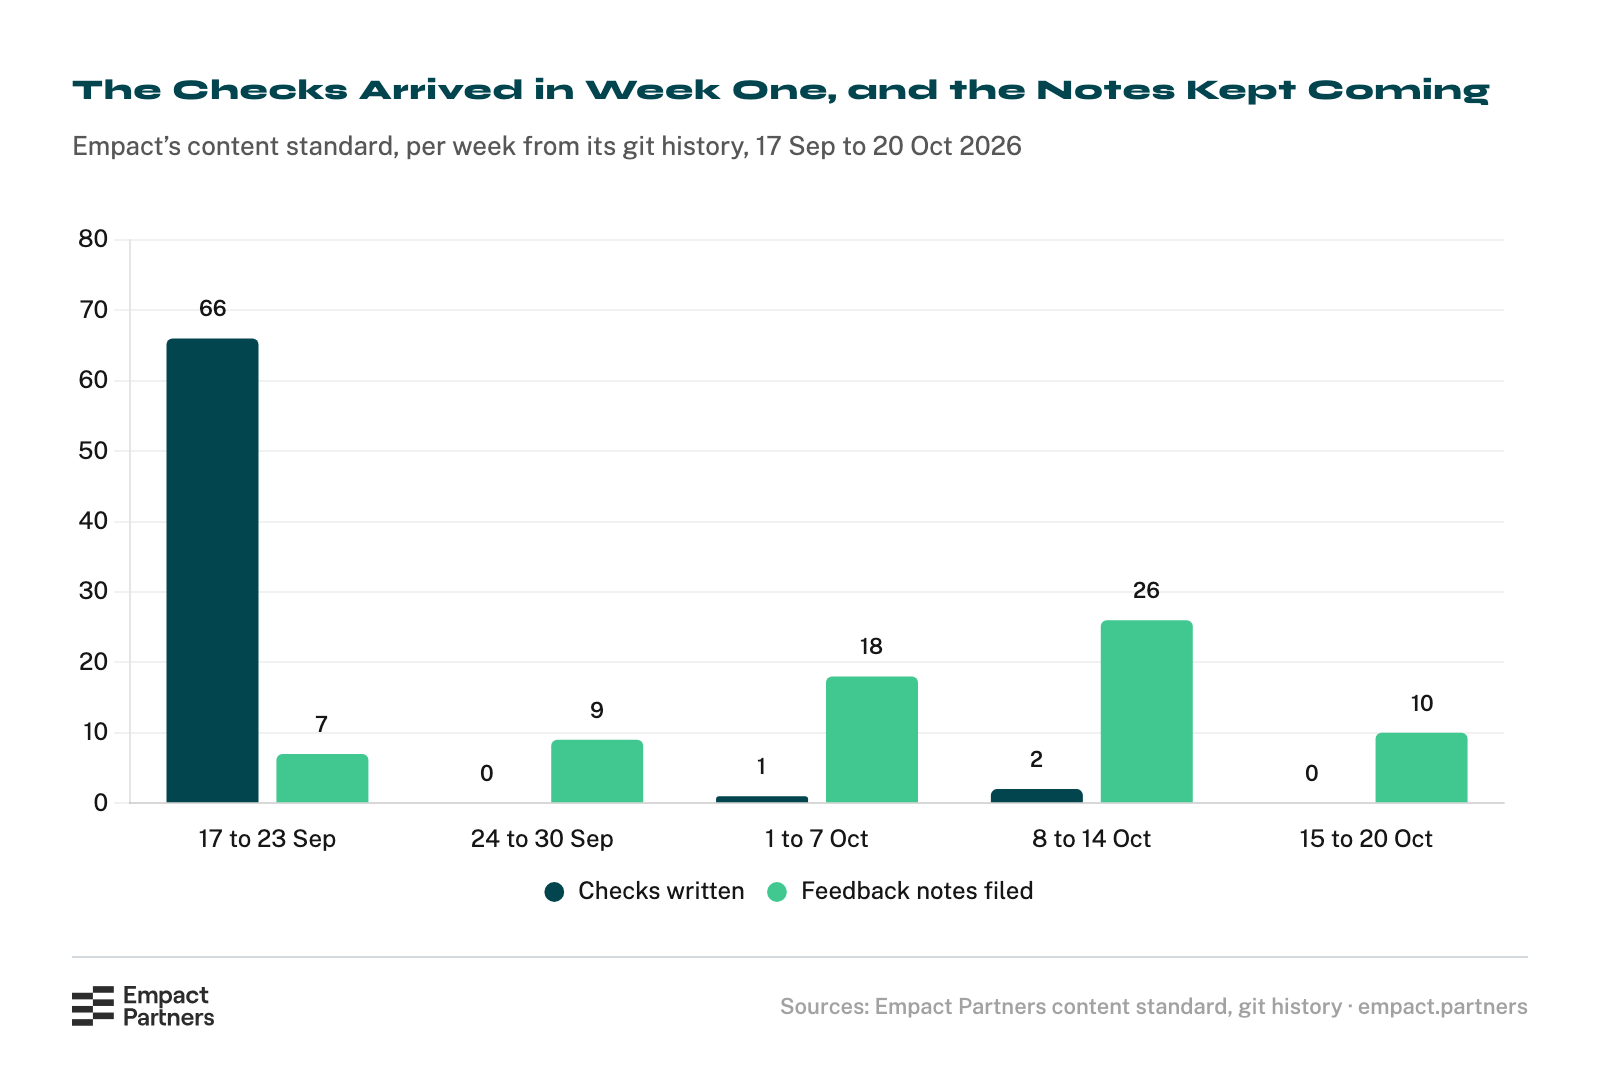
The chart counts rules and notes, which is an input. The number that would settle whether drafts got better is edit rounds per draft, before and after, and we did not keep it. If you start a skill this week, keep that number from the first draft.
With an owner choosing, most notes never became rules. A file that turned every one of them into a rule would end up arguing with itself, the way my memory folder already does. Nineteen of our rules sit struck through, each dated, so the next person with the same bad idea finds it already tried.
One Copy, One Owner, and Everyone Else Files a Note
Sharing is where good skills quietly go bad, and they go bad the same way: copies. On Claude’s own apps, a skill one person uploads is theirs alone. On Team and Enterprise plans, an owner can provision one skill for the whole organization, and anything colleagues share with each other arrives view-only.
Copies drift, and the newest copy is usually the worse one. When our team moved its skills into one repository in September, nine had drifted between someone’s laptop and the shared copy. In seven of the nine the shared copy was the better text, so the obvious rule, newest wins, would have kept the worse version seven times out of nine.
An earlier sync had put a skill edited at ten to midnight onto thirteen laptops by midnight, reviewed by nobody, and zipped copies had gone stale against their folders for a year before anyone looked. The fix is deciding who owns which kind of skill before anything is shared:
| Skills that run a job | The standard they write to | |
|---|---|---|
| What they hold | How to run something: the report, the CMS, the data pull | What good looks like: the voice, the claims, the proof |
| Who changes them | Anyone on the team, with no approval | One owner |
| What a teammate does with a fix | Makes it and commits it, with the history as the safety net | Files it as a note for the owner |
| What breaks without the rule | A tool nobody may fix stays broken | A voice that a dozen people each improve stops being anybody’s voice |
Anyone on our team can change a skill in the shared repository without asking, because the history protects it: a credential scan before anything is shared, hooks that never install themselves, and a revert. The content standard those skills point at runs the other way. A teammate’s correction is logged as a note, and the owner decides.
Somebody has to, because corrections disagree. A practitioner asked exactly this of a skill that edits itself:
“Like if you corrected Claude’s tone in one direction last week but a different direction this week, does it just keep the latest one or does it try to reconcile them?” — u/justserg, r/ClaudeAI, Feb 2026
Neither, if the skill is shared. The person who owns it reads both, decides, and writes down why, so the same disagreement does not get settled again next month in the opposite direction.
None of this needs git. If your writers live in Google Docs, the owner uploads the skill on Claude’s Team plan, everyone gets it switched on, and the notes can live in a shared doc beside it. Describe a check to Claude and it will write the script. We use a repository because our skills already sit next to our code.
Where the Skill Stops and the Consultant Decides
What you can run this week, with the team you have, is one skill built from the fix you have made twice, a log of corrections, and one owner. What a skill cannot carry is the part that makes content worth publishing: what changed in your market this quarter, which angle your buyers have not heard, and whether this draft is ready.
That part is the work, and at Empact Partners it stays with a person. In every Content Marketing partnership, the consultant who owns it brings what nobody else knows about the partner’s market and makes the call on each piece. The skills hold everything that consultant has already decided, so no draft starts from zero.
The proof is the publication, not the tooling. For PDF Reader Pro, two writers built the product guides credited with 15 to 20 percent of its monthly sales. Linearity grew from no organic traffic to more than 250,000 monthly sessions across 400-plus articles in five years. Both predate skills and show the volume a standard has to survive.
A Content Marketing partnership with us opens with an audit of what you already publish and a roadmap. One senior consultant owns it, joins your calls, and works in your channels. Your standard goes into the skills every draft loads: the voice, the claims, and the proof. The work is measured in quarters, not weeks.
The Same Loop Works on Anything Your Team Fixes Twice
None of the method is specific to content. The weekly report, the outreach email, the update a stakeholder has to understand in twenty seconds: anything your team corrects twice wants the same three things, a file that loads with the task, a log of what went wrong, and one person who owns the file.
Empact Partners runs its recurring work on that loop, with each partner’s content standard as the first file every draft loads.
If your team fixes the same draft every week and the brand brief keeps losing, book a call with me, and together we will see whether Empact Partners is the right fit.