


A brand that turns up in an AI answer a week after a Reddit thread went live has proved one thing: it turned up. The answers shift from week to week with nobody posting, the engines read the test itself, and the threads were picked because the brand was already discussed in them. So the screenshot settles nothing.
This page is for the marketing leader handed that screenshot and asked whether it earns another quarter of Reddit work. It shows how to test whether answers citing your threads name the brand more often than answers citing other threads, and why no such test proves the threads caused it. Whether buyers then arrived from a thread is traffic attribution, a separate question.
Empact Partners, a go-to-market consultancy for software companies, runs this test in the Reddit section of the AI Engine Visibility Reports it builds for partners. In our Generative Engine Optimization work we place threads and expert comments where the engines read, so we are the people most tempted to read a screenshot generously. The test was built to refuse us.
A Reddit Citation After Seeding Is Often What the Answers Do Anyway
Start with what the answers do when nobody is testing anything. We track 500 questions a software company asks before hiring outside help with AI search, content or Reddit, our own market, and in October 2026 we put them to ChatGPT, Google AI Mode and Claude five times.
Leave out the 75 questions about Reddit marketing, which cite Reddit because it is their subject, and 425 remain. On Google AI Mode, 266 of those 425 cited a Reddit thread at least once in the five runs. Only 15 cited one every time, and 92 cited one in a single run and in none of the other four.
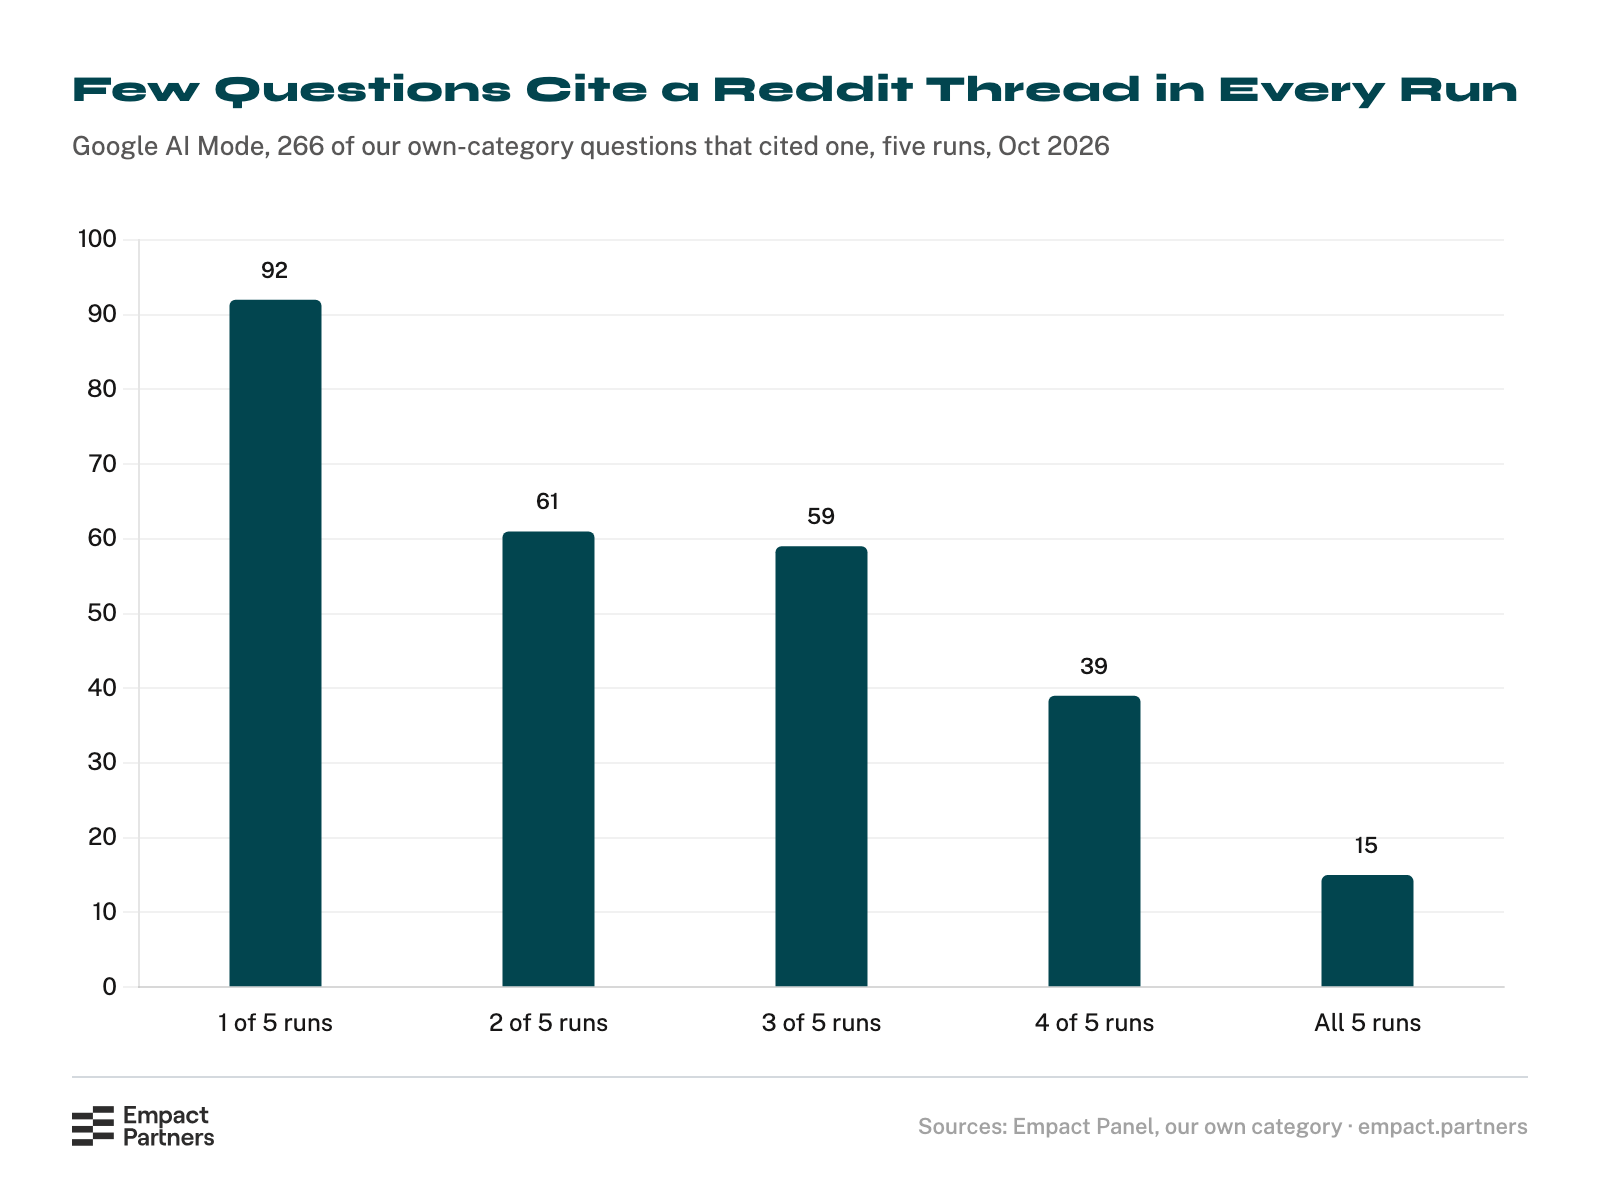
The threads behave the same way. Of the 114 threads AI Mode cited on those questions, 67 appeared in one run only, and none of them named us. A thread that shows up once after it goes live is doing what most cited threads do with no test running at all.
The seeding tests posted on Reddit this year hit a second problem. One case study in r/aeo, a subreddit about getting brands into AI answers, invented a local historian, gave him a website and a YouTube channel, and made the Reddit post announcing the test his third source.
Eight days later a commenter pasted Google’s AI Overview for the question. No such person exists, it said, the title comes from an online experiment, and the source it cited was the experiment’s own thread.
What people on Reddit say about seeding tests
“You probably are aware that ai is able to read Reddit posts correct? Doesn’t this post make your test invalid?” — r/aeo, Aug 2026
“there’s a measurement problem here too. if you’re intentionally seeding brand mentions into reddit and then tracking whether ai starts mentioning the brand, it gets hard to tell whether you improved genuine visibility or just influenced the sources you’re measuring.” — r/aeo, Oct 2026
Both replies point at the same loop: the posts a test plants are themselves sources the engines read. A test that plants mentions and then counts mentions is partly counting its own posts, so the report has to say whether the brand also gained in answers that cite none of them.
Getting a post into an answer is not the hard part. Security researchers led by Qi Liu, in a paper posted to arXiv in October 2026, planted a made-up concept on easy-to-post platforms and found 8 of 10 AI search platforms citing it within seven days. Nothing else on the web carried the name, so it was easy to trace.
A real brand is already named by competitors, reviewers and threads you did not write, and the board’s question is whether your threads changed how often the engines name you there. Answering it takes questions that stay the same from run to run, and a comparison group that cites Reddit as often as yours does.
Count Answers to Questions You Fixed Before the First Thread
The unit is one answer: one tracked question, asked of one engine, on one date. Fix the questions before the first thread goes up and rerun them on a schedule, because a question swapped out halfway changes the sample and moves the number with no help from Reddit. Each answer gets a row:
Read each engine on its own. On our 425 questions Google AI Mode cited a Reddit thread in 622 of 2,094 answers that carried a citation, ChatGPT in 16 of 2,020, and Claude in none of 205. The comparisons are built from cited threads, so an engine that shows almost none leaves the test nothing to read.
Decide before the first run what counts as the brand being named, and match it on the brand’s name and its domain, so a product with a similar name does not count. Never search the raw answer for the name. It carries the source list, so an answer citing the brand’s own page would count as naming it.
Keep questions that contain the brand’s name in their own column, since a question with your name in it tests retrieval, not whether a buyer finds you. Take confidence from the number of questions, not answers: daily answers to one question move together, so our reports resample whole questions.
A Thread Counts From the Minute Your Words Were on It
Even a fixed sheet will credit a thread with answers it could not have touched. A thread is yours from the moment your post or comment exists in it, and a thread on the plan with nothing posted counts nowhere. On one partnership, most threads listed as ours were still empty of us when we first ran the report.
Use the creation time Reddit records for your post or comment, never the date on the plan, which only says when somebody meant to post. Only an answer generated after that minute is eligible to count toward the thread, and our report stops itself if a single answer is counted before its thread’s time.
This matters because the threads engines cite are often old. Comment in one that has ranked for a year and the engines may have cited it many times before your words were there. We have seen a thread where most of its citations came first. Those early answers are kept, because they make the best comparison the test has.
Compare Against Answers That Cite Somebody Else’s Reddit Thread
Comparing the eligible answers with every other answer misleads more than any other choice. Answers that cite Reddit may simply name more brands than answers that cite no forum, and that comparison would credit your threads with the difference.
Your side of every comparison is the same set: answers that cited one of your threads after your words were on it. What changes is the comparison group.
| Comparison | Compared with | What it can establish | What it cannot |
|---|---|---|---|
| Naive | Every answer that cited none of your threads | Whether answers citing you name the brand more often | Whether that is your threads or Reddit’s pull in general |
| Headline | Answers that cited a Reddit thread that is not yours | Whether your threads go with more naming than other people’s threads | Whether you chose threads that already favored the brand |
| Baseline | Answers that cited no Reddit at all | How strongly Reddit goes with naming in your category | Anything about your threads by itself |
| Placebo | The same threads, in answers from before your comment | Whether the gap grew once your words were there | Why the engine named the brand |
The headline gap is the share of your answers that name the brand, minus the share of answers citing other people’s threads that do, in points. Both groups cited Reddit, so it answers the first objection a skeptical CFO raises, that engines citing Reddit name more brands anyway.

The answers that cited your threads before your comment existed go into the comparison group, not outside the test. You chose those threads because the brand was already discussed there, so they tend to name it, and dropping them would make your threads look better. Keeping them errs against your own number.
Report threads you created and threads where you left an expert comment separately, because combining them lets weak results hide behind strong ones. And the headline leaves one difference open: your answers may come from different questions than the ones citing other threads.
The Same Threads Before Your Comment Are the Placebo
The headline still cannot tell a good comment from a good choice of thread. Compare the answers that cited your threads before your comment existed with the answers that cited them after. Same threads, mostly the same questions, and one difference: your words on the page.
Seeding invites the objection this answers, because the threads worth commenting in are the ones where the brand is already discussed. The first time we ran the placebo for a partner, the threads named the brand about as often before our comment as after. Most of the headline gap had been there all along.
That result was still worth reporting, because it identified the threads the engines lean on when they name the brand. It did not show that the comment did the work. Every report sorts the placebo into one of three outcomes, each permitting a different sentence:
Set the rules before anyone sees the numbers, because a placebo result read afterwards can be argued into any of the three.
Choose the Metric and the Refusal Rules Before Anyone Looks
Pick the measure before the first number comes back. Where the brand is already named in most answers, the naming rate has almost nowhere to go, and a working program can look flat. Our reports switch to share of voice when the brand is named in over 60% of comparison answers, or has under 20 points of room.
Written down first, that rule also stops anyone reporting whichever measure happened to move. Then decide when the test refuses to report a lift. Ours refuses when any of these falls short:
Those six thresholds are our defaults. When a result falls short, the report still shows the table of groups, the counts and the reason, and leaves out only the multiplier and the confidence claim. A null result that quietly goes missing is how a program comes to look as if it always worked.


No Test of This Kind Can Show the Thread Caused the Answer
Pass every one of those rules and the test has still not shown cause. The engines do not say what they read and weighed, so the timestamp proves your words existed, never that the engine read them. And the threads were chosen, not assigned at random, so they differ from the ones you skipped in ways no comparison removes.
The window carries its own changes. A model update can move answers citing your threads differently from those citing other people’s, while the headline assumes both groups move together. A review site that copied your thread can carry it into answers that never cite Reddit, where no comparison sees it.
So the report says this much and stops. Between these dates, answers citing our threads after our comment went up named the brand this many points more often than answers citing other threads. The same threads named it less often before. That is an association in time, and it is as far as the test goes.
Running It Every Month Is the Larger Half
Reported month after month, that association is what tells you whether to keep the program running, and part of the record can start this afternoon:
The rest takes quarters. You need enough questions whose answers cite your threads, enough days with your words live, and threads the engines cited before you commented. Somebody has to own that record from the start, because answers nobody collected in March cannot be collected in June.
Keeping that record is part of the Generative Engine Optimization work Empact Partners runs for partners. We start by auditing the questions buyers ask and the threads the engines already cite for them. Then we place threads and expert comments, and Qvery, our sister company, reruns the tracked questions daily. We built Qvery, so discount our word and check the counts under every figure.
The monthly report prints all four comparisons, the placebo outcome and every refusal, and a named senior consultant reads it with the partner over quarters, not weeks. If your board is being shown Reddit screenshots with no test behind them, book a call with me. Between us we can work out whether this is ours to run.


